AI tools with test and evaluation built in
More productivity with less AI spend.
When an AI capability isn't working, we find out whether the problem is the model, the data or the workflow, and we fix it. We specialize open models, build agents that automate the work, use plain software wherever AI isn't needed, and independently test every piece.
Leading an AI effort at a company? Work with Scott directly.
- Department of War & ICMission focus
- TS/SCIClearance level
- SDVOSBCertified
- TradewindsApproved
- CAGE 10WJ5SAM registered
- 2023Founded
When AI isn't working
We usually get the call when an AI capability isn't delivering. The first job is finding out why.
-
The data.
This is the most common cause. We fix the data, or change how the AI reads it.
-
The workflow.
AI was bolted onto a human process and expected to do exactly what a person did. We redesign the work around what AI does well, and use deterministic software for the steps that don't need AI.
-
The model.
When the model is the gap, we specialize an open model for the task with LoRA adapters.
We run model test and evaluation and workflow evaluation together, so the fix lands in the right place.
What we do
Capabilities
AI Eval Corp builds mission AI tools and evaluates AI systems across classification levels. Both sides of the work share one standard: evidence a decision maker can defend.
What we build
Four pieces, one goal: more productivity with less AI spend.
-
Specialized open models.
We tune open models to your task with LoRA adapters, so you aren't paying for a large general model to do narrow work.
-
Agents that automate workflows.
Agents take on the repetitive steps people do today.
-
Deterministic software where AI isn't needed.
Our agents write plain code for lookups, rules, math and formatting. Same input, same output. It runs the same way every time, with no model cost.
-
Independent testing of all of it.
We test the models, the adapters, the agents and the generated code before anything ships.
Our fee is small compared to the productivity gain and the costs we cut.
Mission tools we've built
-
Speech-to-structured-record pipelines
Turn spoken reports and conversations into structured records that people and downstream systems can use.
-
Course-of-action planning and decision support
Tools that help planners develop, compare, and assess courses of action.
-
Offline and air-gapped AI packages
AI capabilities packaged to run on disconnected and classified networks, with no dependence on outside cloud services.
-
Offline LLM evaluation
Evaluate large language models fully offline, inside the environment where the model will be used.
What we evaluate
-
Workflow evaluation
We test the whole workflow, not only the model, to find whether the model, the data or the process is holding the capability back.
-
AI test and evaluation
Vendor-agnostic evaluation of AI/ML models against mission-specific requirements: evaluation design, metrics, test campaigns, and findings stakeholders can act on.
-
Verification and validation
Evidence that a system was built to its requirements and that it meets the operational need.
-
Acquisition readiness
Evaluation criteria, evidence requirements, and go or no-go assessments that support acquisition and fielding decisions.
-
Evaluation infrastructure
Modular evaluation harnesses that run test campaigns across cloud and air-gapped environments, using frameworks such as HELM and EleutherAI's evaluation harness.
-
Continuous monitoring
Ongoing assessment of deployed AI systems to catch model drift, performance degradation, and emergent behaviors before they affect the mission.
-
Benchmark development
Custom benchmark suites for mission-specific use cases, aligned to NIST and MLCommons standards.
-
Cross-classification delivery
Work delivered across classification levels, from unclassified cloud environments to SECRET and TS/SCI air-gapped networks.
An example
An AI built to produce intelligence summaries was pulling in everything it could find in the database. Most of it had nothing to do with the finished product, and the output wasn't usable. We trimmed the input to only the data that belongs in that product, and gave the model examples of a finished summary. The output cleaned up, and end users could rely on the automation.
How we work
Test and evaluation is part of development, from the start.
Every model, agent and line of generated code is built against measurable mission criteria and ships with the evidence behind it.
-
Mission-driven scoping
Every effort starts with operational context. Program managers and end users define what "good enough" means for their mission, and that becomes measurable evaluation criteria.
-
Evaluation designed before the build
Metrics, test data, and acceptance criteria are set before development begins, so each build is measured against the mission, not against a demo.
-
Verification and validation throughout
Each release is verified against its requirements and validated against the operational need, with documented methodology and reproducible results.
-
Actionable, auditable reporting
Findings in language acquisition leaders can act on: clear risk characterizations, specific recommendations, and go or no-go assessments tied to mission requirements. Methods are built to be auditable by third parties and defensible in acquisition decisions.
-
Independent evaluation
When AI Eval Corp evaluates a system it did not build, the findings stand on their own. AI Eval Corp does not resell third-party platforms or take vendor referral fees.
Areas of expertise
Who we are
About AI Eval Corporation
AI Eval Corporation was founded in 2023 in Fairfax Station, Virginia, to build and evaluate AI for national security missions. It is a certified SDVOSB.
We work for the Department of War, including CDAO, OUSD(I&S) and NGA, and support the CDAO Rapid Test and Evaluation Cell under a Johns Hopkins APL subcontract. Our approach comes from nearly two decades of hands-on AI test and evaluation, from Army Research Laboratory sensor and imagery testing to Project Maven.
For contracting officers
Contracting details
| Legal name | AI Eval Corporation |
|---|---|
| Founded | 2023 |
| CAGE | 10WJ5 |
| UEI | X5ADU33483Z5 |
| Socioeconomic status | Certified SDVOSB; Small Business (SBA) |
| Registration | SAM.gov registered |
| Tradewinds | Approved |
| Clearance level | TS/SCI |
| Primary customer | Department of War |
| Address | 8121 Rondelay Ln, Fairfax Station, VA 22039 |
| Phone | 703-424-0796 |
| scott@aieval.org |
Leadership
Scott Mastin, President
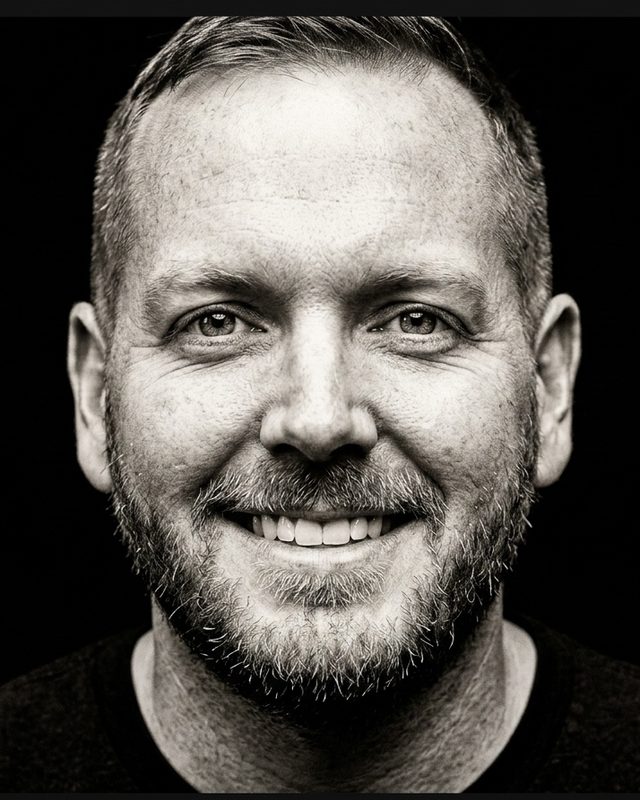
Scott Mastin leads AI Eval Corporation. He manages AI test and evaluation programs for the Pentagon and has worked in AI test and evaluation since 2007. He is a service-disabled veteran.
- AI test and evaluation program manager for Project Maven at the Algorithmic Warfare Cross-Functional Team (AWCFT), across all lines of effort, 2019 to 2023
- Maven test and evaluation lead through Maven's move to CDAO and NGA, 2023 to present
- CDAO Rapid Test and Evaluation Cell work under a Johns Hopkins APL subcontract
- Army Research Laboratory sensor and imagery AI testing, 2007 to 2019
Leading an AI effort at a company? Work with Scott directly.
Scott works with company leaders whose AI isn't paying off. He finds whether the problem is the model, the data or the workflow, and helps cut AI spend without losing what works. More at scottmastin.com.
Start with a 30-minute intro.
Have an AI capability that isn't delivering, a workflow you want automated, or a system that needs an independent assessment? Tell us what's in front of you.
-
Book a call
Book a 30-minute intro -
Email
Prefer email? scott@aieval.org -
Phone
703-424-0796 -
LinkedIn
AI Eval CorporationConnect on LinkedIn